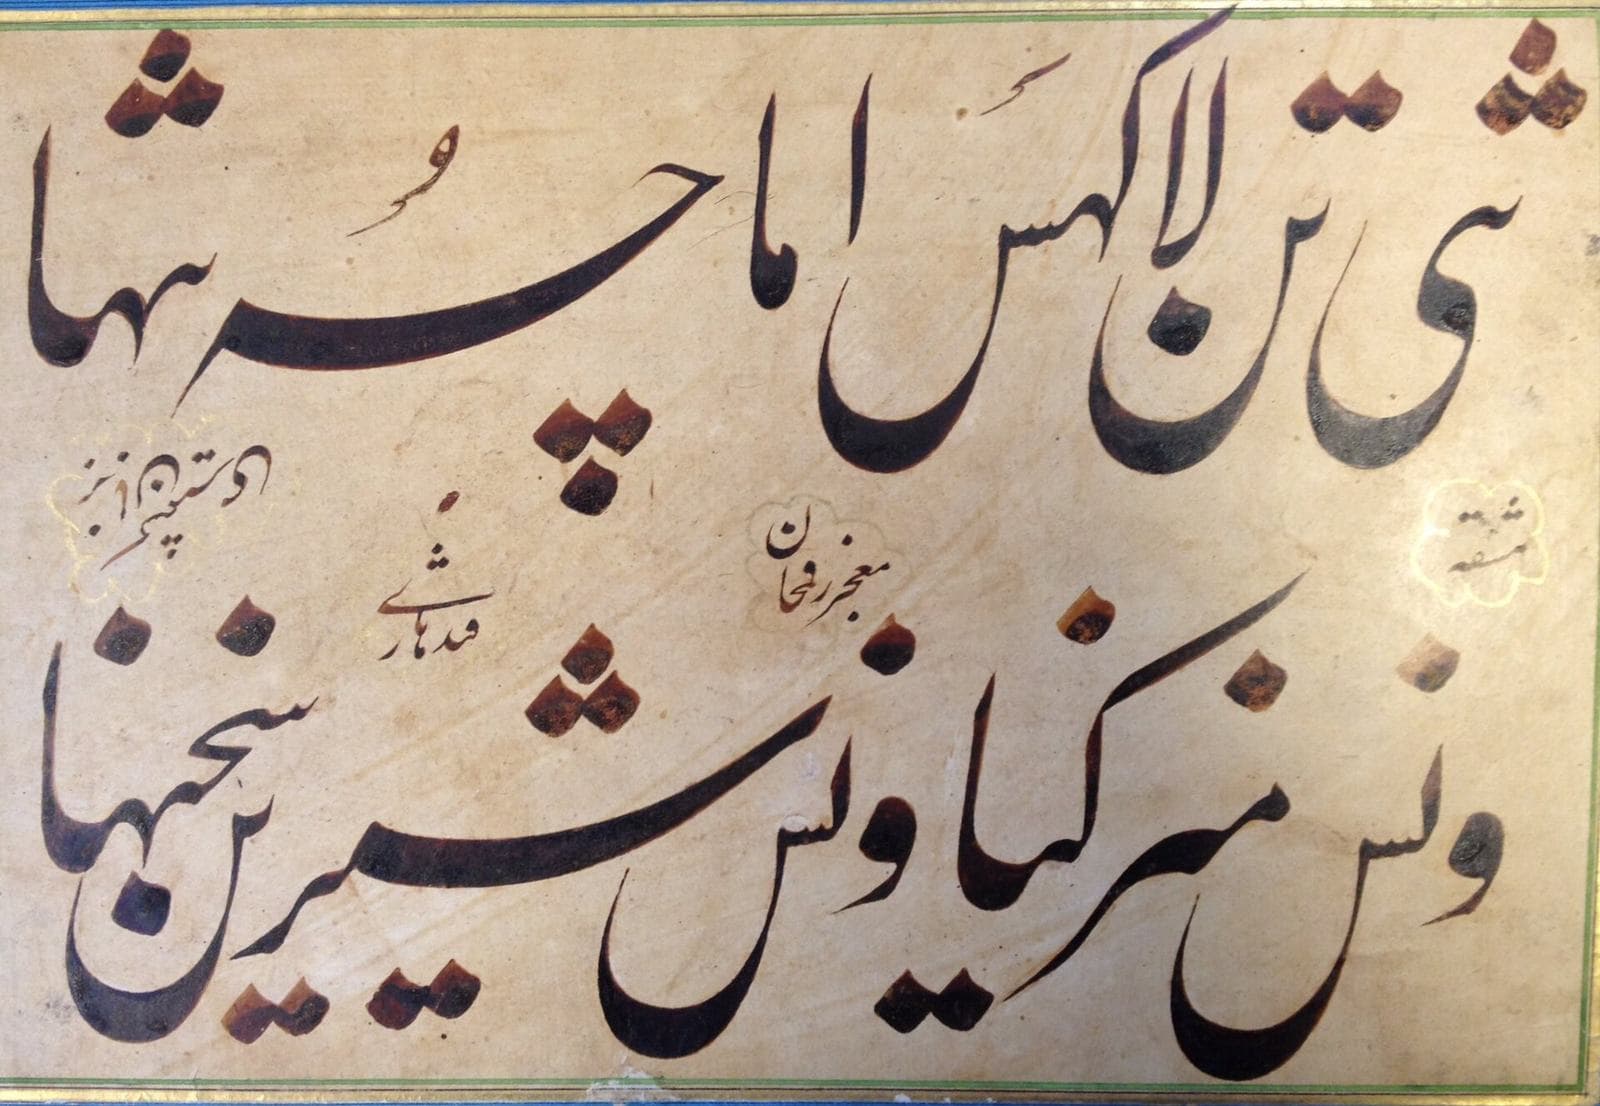
Which script Kashmiri is written in
Kashmiri is written mainly in a modified Perso-Arabic script, usually in the Nastaliq style and read right to left, as in the language's own name, کٲشُر (Koshur). The Jammu and Kashmir government recognises it as the official script. It is not simply Urdu's alphabet: Kashmiri marks its vowels far more fully, so it adds vowel letters such as ٲ and ۄ. Before the shift to Perso-Arabic, which grew in the 19th century, Kashmir's older script was Sharada, used above all for Sanskrit. Since 1990 some Kashmiri Pandits have written Kashmiri in Devanagari, and online many people type it informally in Roman letters.
Each script has different Unicode support, fonts and amounts of digital text, and that decides how well software and AI models handle it. Benchmarks such as FLORES-200 already treat kas_Arab and kas_Deva as separate entries, so a score for “Kashmiri” means little until you know the script. The full story is in our history of Kashmiri's scripts.
How Unicode encodes Kashmiri
Unicode has no separate Kashmiri block. Perso-Arabic Kashmiri uses the Urdu letter set plus a few characters of its own in the Arabic block, chiefly U+0620 ARABIC LETTER KASHMIRI YEH and the vowel mark U+065F WAVY HAMZA BELOW, both added in Unicode 6.0. Devanagari has dedicated Kashmiri vowels (U+0973–U+0977 and their vowel signs), and Sharada gained eight Kashmiri vowel signs only in Unicode 17.0 in 2025.
The practical problem is variants. The deprecated U+0673 and the recommended sequence U+0627 + U+065F look the same, as do Arabic and Farsi yeh, or kaf and keheh, yet no Unicode normalisation form merges them. Search, dataset filters and tokenisers then treat one word as several. Our post on the Kashmiri letters and vowel signs Urdu doesn't have lists each character and gives a folding step to run before indexing or training.
Typing Kashmiri correctly
As of October 2026, Gboard on Android and the built-in keyboards on iPhone, iPad and Mac include Kashmiri in both Perso-Arabic and Devanagari. Windows has no Kashmiri layout and assigns the Urdu keyboard, which lacks letters such as ٲ, ۄ and ؠ; the standard Linux input method lacks them too. Fonts matter as much as keyboards: Noto Nastaliq Urdu from Google Fonts contains every Kashmiri character we checked, while some common fonts do not.
Many keyboards slip in look-alike Urdu, Arabic or Pashto characters that display correctly but break search and translation. How to type Kashmiri on your phone and computer covers each platform, the fonts we tested and the substitutions to avoid.
Legacy InPage files
For years InPage was the practical way to set Nastaliq on screen and in print, so a large share of typed Kashmiri exists only as .inp files in InPage's own, undocumented encoding. Those files cannot be searched or used as training data until they are converted. The converters we found were built for Urdu: Kashmiri letters and vowel signs can be dropped, passed through as stray codes or swapped for Urdu look-alikes without warning.
Converting InPage Kashmiri files to Unicode sets out a workflow and a character-by-character checklist for the output. A Kashmiri-aware converter is described on our digitisation page; it is planned, not built.
OCR for print and manuscripts
There is no mature, general-purpose OCR system for Kashmiri. Nastaliq's sloping words, overlapping ligatures and small vowel marks are hard for engines built for Latin or Naskh text, and Tesseract publishes no Kashmiri model. Most public work dates from 2025–2026: large synthetic datasets for printed Perso-Arabic Kashmiri and a few baseline models whose authors report high error rates, especially on real scans. Handwriting and Sharada manuscripts are much less covered.
Kashmiri OCR: where things stand lists each dataset and model with its authors' own results and licence. The same resources, with links, are in the Resource Hub.