Seven million speakers.
Almost no machine that understands them.
Kashmiri is a scheduled language of India, written in Perso-Arabic Nastaliq, and almost absent from modern language technology. Kashmir AI Research builds the missing pieces — a corpus, a benchmark, and a place for native speakers to judge the results.
کٲشُر
- 7M+
- Kashmiri speakersand counting
- 124,102
- Sentence pairsaggregated & filtered
- 205
- Resources catalogued1932–2026
- 31.57
- BLEU, NLLB-200 baselineICRTC-2026 test set
What a machine sees
Before a model can translate a sentence it cuts it into pieces it knows. A general-purpose model knows so few Kashmiri pieces that it shatters the language into fragments, some of them raw bytes. A model built for translation keeps far more of each word whole.
سُہ چھُ آز اکھ کامیاب ویب ڈزاینَر۔
“He is a successful web designer today.”
Mistral-7Bgeneral-purpose LLM
36 pieces · 5.1 per word · 2 raw bytes
- ␣
- س
- ◌ُ
- ہ
- ␣
- چ
- ھ
- ◌ُ
- ␣
- آ
- ز
- ␣
- ا
- ک
- ھ
- ␣
- ک
- ا
- م
- ی
- ا
- ب
- ␣
- و
- ی
- ب
- ␣
- ڈ
- ز
- ا
- ی
- ن
- ◌َ
- ر
- DB
- 94
NLLB-200translation model
15 pieces · 2.1 per word
- س
- ◌ُ
- ہ
- چھ
- ◌ُ
- آز
- اکھ
- کامیاب
- ویب
- ڈ
- ز
- این
- ◌َ
- ر
- ۔
Englishthe same sentence, Mistral-7B
8 pieces · 1.1 per word
- He
- is
- a
- successful
- web
- designer
- today
- .
Best Paper Award
ICRTC2026
Best Paper
Anatomy of Decoder-Only LLM Failure in Low-Resource Machine Translation
Faizan Ayoub and Neha Prerna Tigga · ICRTC-2026, in association with Springer. The paper reported a tokenizer-fertility analysis for Kashmiri, a data threshold for cross-lingual transfer, and a decoding strategy worth +12.75 BLEU. Follow-up work (2026) is re-testing these results; the details will appear in a follow-up paper.
What we are building
Kashmir AI Research is teaching AI to understand Kashmiri: finding the data, measuring models honestly, translating in both directions and asking native speakers where machines still fail.
- 1Find the data: Live
- 2Build the corpus: In progress
- 3Measure honestly: In progress
- 4Translate both ways: In progress
- 5Ask native speakers: Live
- 6Write it right: Planned
- 7A model that knows Kashmiri: Planned
- 01
Find the data
Map every Kashmiri dataset, paper, model and tool that exists, so nothing is rebuilt twice.
- 02
Build the corpus
124,102 Kashmiri–English sentence pairs, aggregated from AI4Bharat BPCC and the SMUQamar corpus, then deduplicated and filtered on length and script. It is the training set behind the ICRTC-2026 models; the sources are credited and the merged data is not redistributed.
- 03
Measure honestly
A QLoRA-adapted Mistral-7B measured against NLLB-200 and IndicTrans2. The headline result is a negative one: a 600M translation model beats a fine-tuned 7B LLM, and we traced exactly why.
- 04
Translate both ways
Kashmiri into English, and English into Kashmiri — the harder direction, where spelling matters.
- 05
Ask native speakers
Automated metrics punish valid Kashmiri paraphrases. So native speakers rate translations here directly — blinded, randomised, with agreement tracked.
- 06
Write it right
Handle Kashmiri's spelling variation and vowel marks, and bring old typed and handwritten text into Unicode.
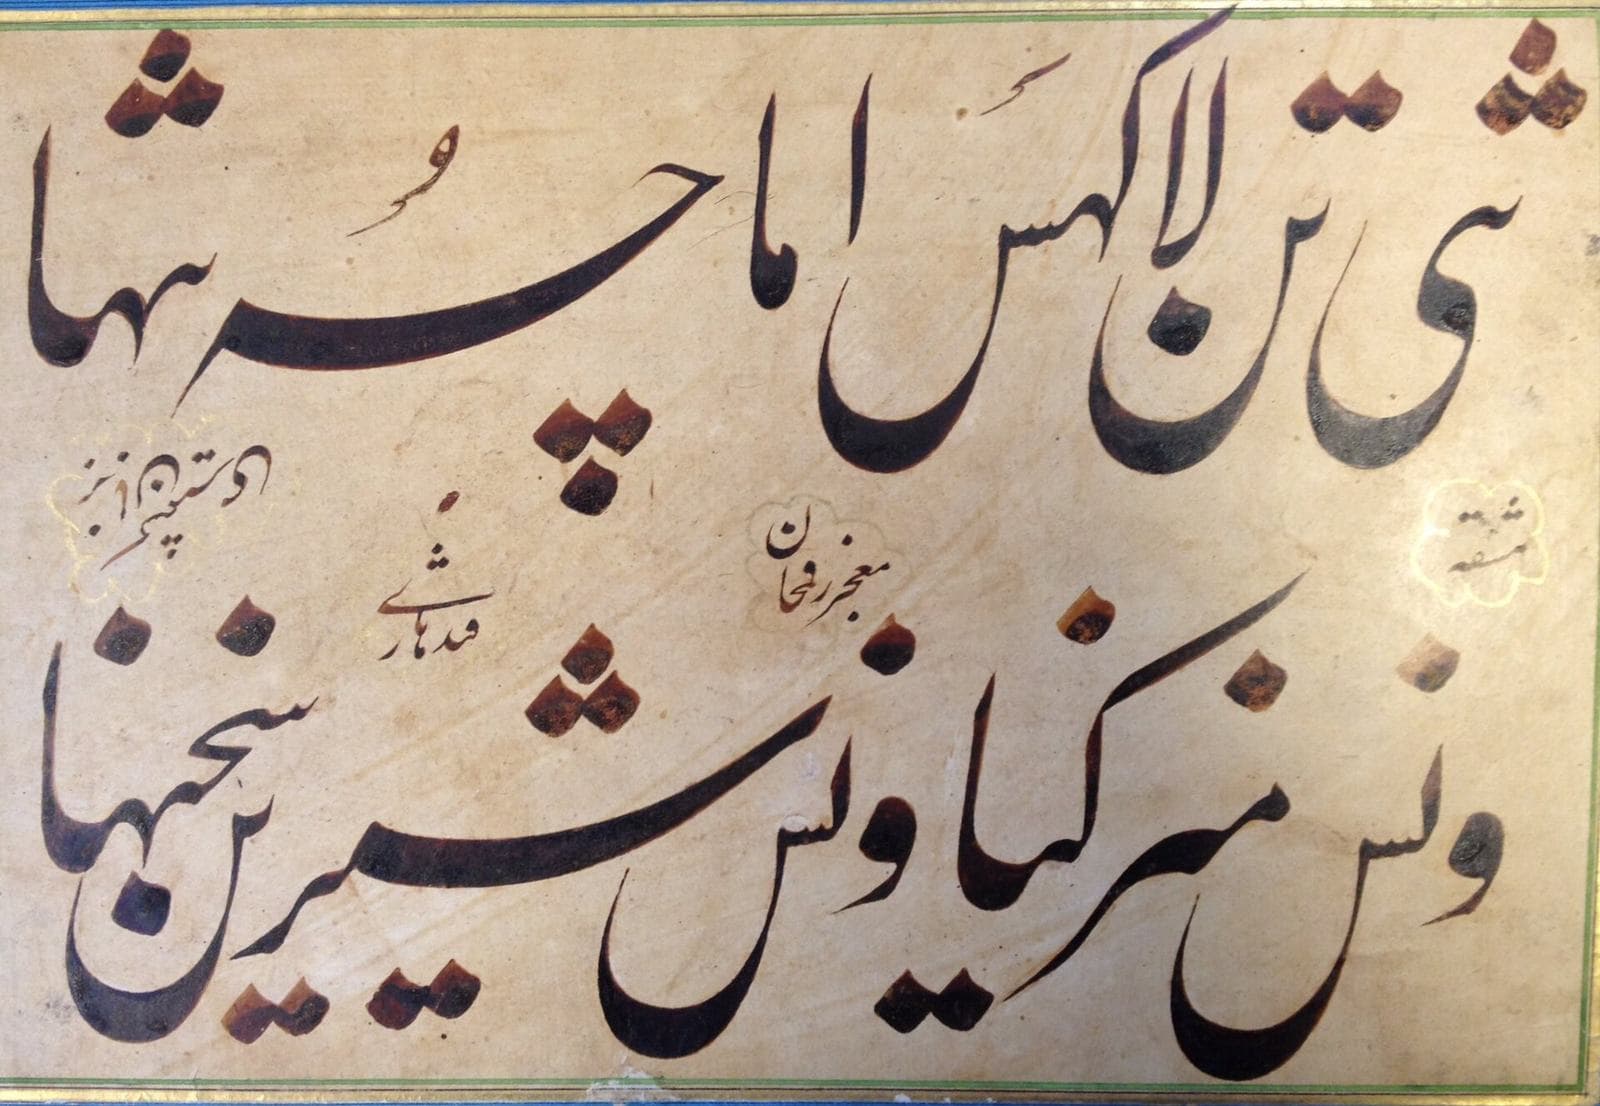
Nastaliq calligraphy by Muʻjiz Raqam Khan Qandahari, Delhi, mid-19th century — the script Kashmiri is written in today.Muʻjiz Raqam Khan Qandahari, Public domain, source - 07
A model that knows Kashmiri
Teach language models more Kashmiri by letting them read clean Kashmiri text before they translate.
Papers in preparation
A contamination-controlled benchmark
KashEval: Kashmiri test sets kept apart from every known training corpus, so scores mean what they say.
English → Kashmiri translation
The harder direction, scored in a way that does not punish valid Kashmiri spelling.
Re-testing the ICRTC-2026 findings
A follow-up study re-running the award paper's results; the details will appear in a follow-up paper.
A clean Kashmiri text corpus
Every openly licensed source of Kashmiri text, pooled, cleaned and checked against test sets.
Guides
Kashmiri text technology
How Kashmiri is written, encoded and typed: its scripts, the Unicode letters Urdu lacks, keyboards, InPage conversion and the state of Kashmiri OCR.
Kashmiri machine translation
Who translates Kashmiri, why quality is low, tokenizer fertility, the ICRTC-2026 paper and how native speakers evaluate Kashmiri machine translation.
Kashmiri language data
Where Kashmiri language data lives: parallel corpora, monolingual text, speech datasets, test sets and the licences that govern each.
If you speak Kashmiri, you can do something no model can.
You do not need a technical background. Read a Kashmiri sentence and three computer translations of it, score each one and mark its mistakes. A pack of 25 sentences takes about an hour, saves as you go, and shows us exactly where AI still fails Kashmiri.
Start with a five-minute consent form.
Everything built for Kashmiri, tracked in one place
Kashmiri research is scattered across arXiv, HuggingFace, government portals and university PDFs. The resource hub catalogues all of it — 205 datasets, papers, models, tools and the groups behind them, filterable by task and year, and open to submissions.
Browse the catalogue